PDF Question-Answering Bot
Load a set of PDFs, chunk and embed them in ChromaDB, and build a command-line assistant that answers questions strictly from their contents and says so when it cannot.
- Python
- ChromaDB
Learn RAG (Retrieval-Augmented Generation) in Phagwara — chunking, embeddings, vector search and grounded answers — with live projects and placement support.
25,000+
Students trained
since 2007
4.9★
Google rating
556+ reviews
100%
Practical training
live client work
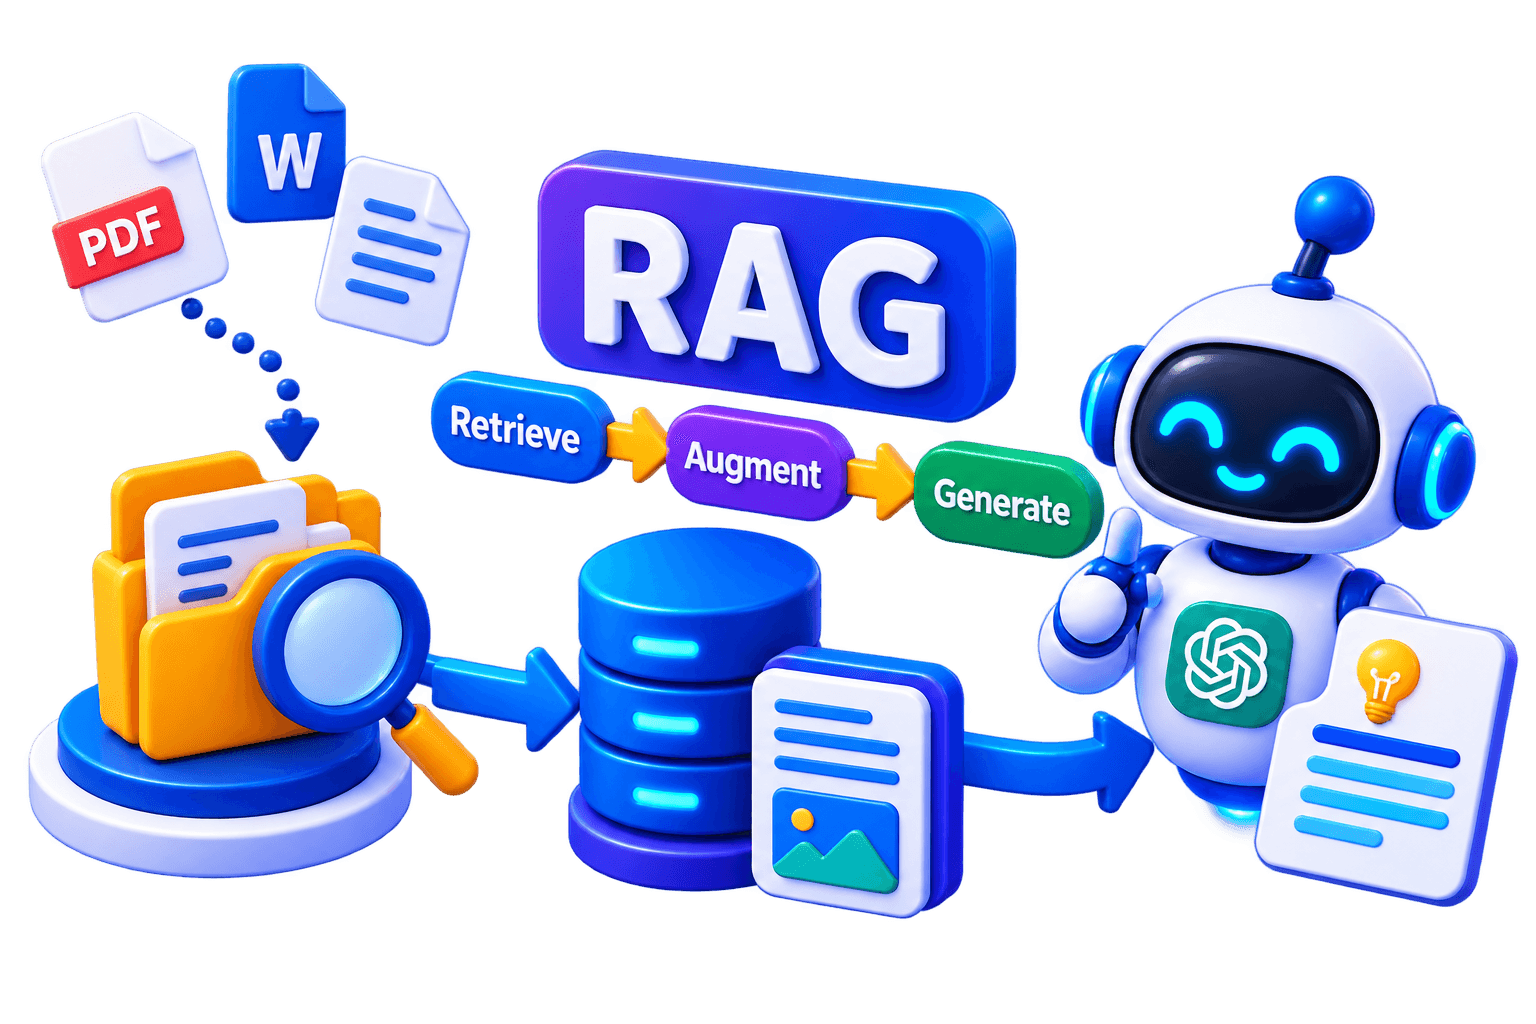
Techcadd’s RAG (Retrieval-Augmented Generation) Course in Phagwara is a specialist programme for developers who need a language model to answer from a specific body of documents — a policy manual, a product catalogue, a case file — instead of from whatever it happened to memorise in training. It begins with the reason retrieval usually beats fine-tuning for factual work, then moves into document parsing and the chunking decisions that quietly decide how good your results can ever be. Embeddings and similarity search follow, then vector databases and indexing in Pinecone and ChromaDB, query rewriting, hybrid search and re-ranking, and grounded answering with citations so every answer can be checked against its source. A full module is given to evaluation and hallucination testing, the part most tutorials skip entirely, before the programme closes with production deployment and scaling using Python, LangChain, LlamaIndex, Hugging Face, FastAPI, Claude and the OpenAI APIs. You build one real retrieval system across the whole course, reviewed by a trainer at each stage, and leave the Phagwara centre with a working, measured application, a documented internship and CV and interview preparation for AI Engineer and RAG Developer roles.
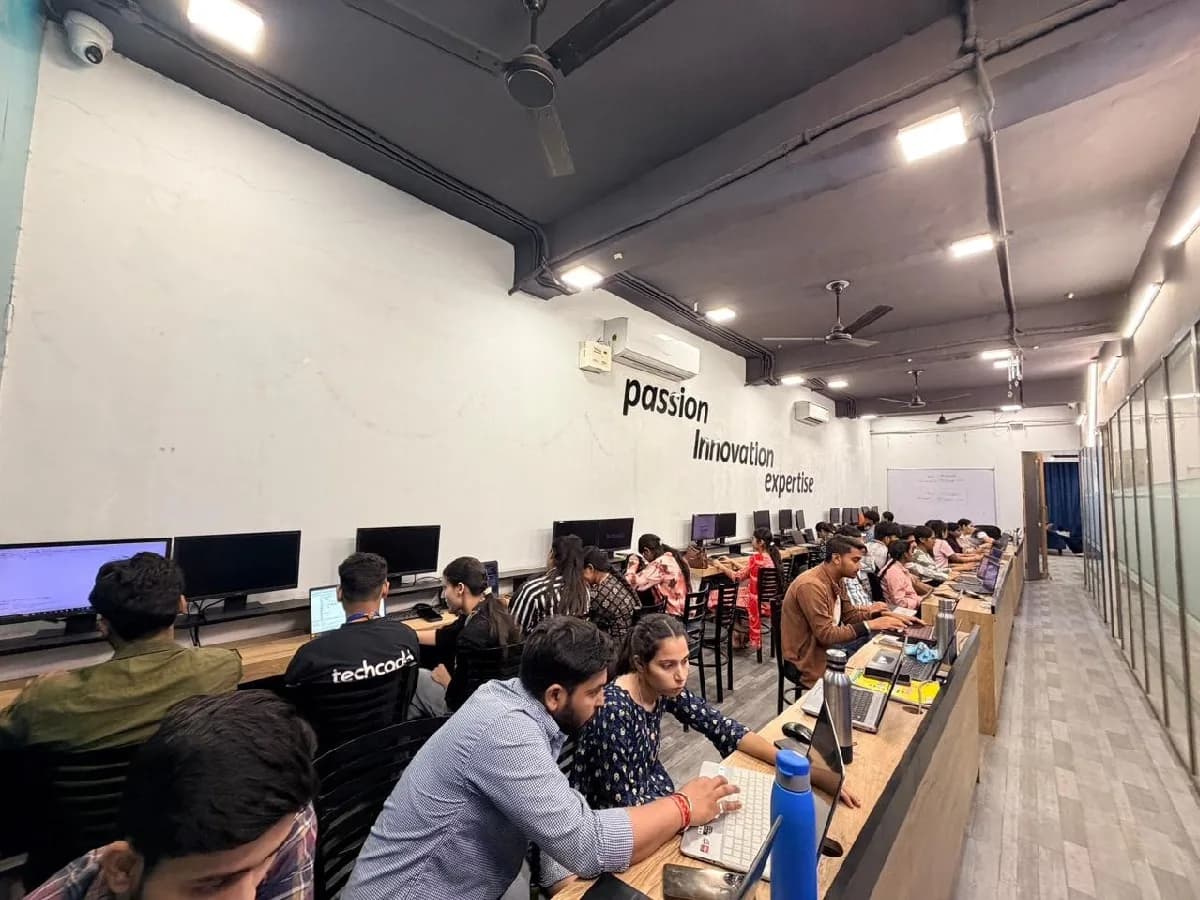
The RAG Development course is built for people at six different starting points, and the batch is deliberately mixed. What matters far more than your background is turning up consistently and finishing what each module asks you to build.
You can already write code, and now every client wants “ChatGPT on our documents”. This course gives you the retrieval layer — chunking, vectors, grounding and evaluation — that turns a demo chatbot into a system that answers correctly and can prove it.
If you are studying B.Tech, BCA or MCA at LPU, GNA University or a college around Phagwara, a deployed RAG application is one of the strongest final-year projects you can carry into placement season. It shows systems thinking, not just a trained model.
You know models; RAG is where models meet real documents. Data analysts and ML engineers use the course to move into LLM application work, where the demand in 2026 is, without abandoning what they already know.
Backend developers, QA engineers and support engineers in Phagwara, Jalandhar and Kapurthala take the weekend batch to add an AI specialisation while staying employed. The API and deployment modules map directly onto the work you already do.
Immigration consultancies, schools, hospitals and export firms around Phagwara all sit on years of documents nobody can search. Understanding how a knowledge assistant is built lets you commission one properly — or build the first version yourself.
Document Q&A bots, internal knowledge assistants and support automation are among the most-posted AI briefs on freelance platforms. RAG is a skill you can scope, price and deliver remotely from Phagwara to clients anywhere.
RAG is the most requested AI build in Indian companies right now, because it is how internal knowledge tools get made — and in Punjab the firms that want one far outnumber the developers who can build one that answers correctly. That gap is the whole argument for this course: there is local demand, there are budgets, and there are very few trained people to hand the work to.
Build skills that hold up beyond the classroom.
What separates this from a playlist of tutorials is supervision on real work. From the second half of the course you build on live client projects with a trainer beside you, make decisions that have consequences, and correct them the following week. That loop is the skill. No employer in Phagwara will take your word for it without work they can inspect.
Be realistic about the money. A fresher who finishes with a working portfolio starts near the bottom of the band and moves quickly; someone who finishes with a certificate and nothing to show does not. The difference is entirely what you built.
The alternative is what most people try first: free videos, a cheap online course, six months of drifting, and knowledge you cannot demonstrate. A structured programme with live projects, a mentor who corrects you, an internship letter and a placement cell that actually calls employers is the difference between knowing the subject and being hired to do it.
Students reach the Phagwara centre from Banga, Nakodar, Kartarpur and the university belt, and the weekend batch exists so a job or a degree does not have to be paused to attend.
Internal knowledge assistants, policy Q&A, support bots over product manuals, research tools over case files — nearly all of them are RAG underneath. Learning it well puts you on the most common AI project in the market.
Most RAG demos fail on retrieval, not on the model. The programme spends real time on parsing, chunking, embeddings, hybrid search and re-ranking, because that is where answer quality is actually decided.
You build a test set, score faithfulness and retrieval quality, and run regression tests — so when a client asks “how do you know it is right?”, you have numbers rather than a shrug.
LangChain, LlamaIndex, Pinecone, ChromaDB, FastAPI, Docker and Git are the stack real teams use. You finish with a deployed API and a repository an interviewer can clone.
Instead of nine disconnected exercises, you build a single retrieval application across the programme on a genuine document set, with a trainer reviewing each layer as you add it.
You also learn when long context, fine-tuning or plain search is the better answer. Knowing the limits of the technique is what separates an engineer from a tutorial follower.
The syllabus is arranged so every module produces an asset rather than a set of notes. You will cover why retrieval: llm limits & the rag architecture, document parsing & chunking, embeddings & similarity search, vector databases & indexing, and finish with a live project built on Python, LangChain, Pinecone. Modules run in the order a real project runs: foundations first, then the core skills, then applied work under supervision, then the portfolio and interview preparation that turn all of it into an offer letter.
The working knowledge the job description actually lists.
Embeddings & Similarity Search
Learn how text becomes vectors, how similarity is measured, and how to choose an embedding model for your data and budget.
3 weeks · 12 sessions
Vector Databases & Indexing
Store, index and filter millions of vectors in Pinecone and ChromaDB, and keep an index current as documents change.
3 weeks · 12 sessions
Query Rewriting, Hybrid Search & Re-ranking
Improve what gets retrieved before the model ever sees it — better questions, better candidates, better ordering.
3 weeks · 12 sessions
Topics covered
The toolchain behind the craft
Everything below is installed on the lab machines and used on live client work, not shown once in a slide and forgotten.
Complete the course with a portfolio of live projects and receive an industry-recognised certificate, plus a documented internship letter accepted by Punjab universities.
Recognised by employers across Punjab and beyond
Based on real client work, not a simulation
Live work you can show in any interview
CV review, mock interviews and hiring drives
Two certificates on completion — the course certificate and a separate capstone project certificate.
The roles this opens, what they pay in Punjab and beyond, and who is hiring for them — drawn from published job-market listings on one comparable scale, not a brochure number.
Salary outlook
Builds retrieval-augmented applications — document pipelines, vector search, grounded answering, evaluation and deployment. Earnings vary with your Python depth, portfolio, evaluation discipline, company, location and the systems you have shipped.
Punjab — RAG / AI Engineer
Delhi / NCR — AI Engineer
Remote / Freelance RAG Work
Indicative ranges for RAG / AI Engineer roles, compiled from public job-market listings and drawn on the same scale in every market. Actual offers vary by employer, skillset and interview performance — Punjab pay typically reaches 2× the fresher ceiling within two years of delivery experience.
Talk about your target roleAI Engineer, RAG Developer, ML Engineer, AI Solutions Consultant, LLM Application Developer and Knowledge Systems Developer. Because RAG is how internal knowledge tools get built, it is the most common line on Indian AI job postings, and a deployed, evaluated project counts for more than any certificate.
A fresher with a working retrieval system on GitHub starts around ₹25,000 – ₹45,000 a month in the Punjab market and reaches ₹45,000 – ₹90,000 with two years of delivery experience. Delhi/NCR runs materially higher, and engineers who can show evaluation numbers move fastest.
Yes — document Q&A bots and internal knowledge assistants are among the most-posted AI briefs on freelance platforms, and a Phagwara address costs nothing on a remote contract. Freelance income starts lower, around ₹20,000 – ₹40,000 a month, and climbs to ₹60,000 – ₹1,50,000+ once you have delivered systems clients can vouch for.
IT services firms building AI features for clients, startups shipping LLM products, and increasingly the organisations that own big document archives — immigration consultancies, schools and universities, hospitals, legal practices and export houses across Phagwara, Jalandhar and the Doaba region — plus remote clients.
No. RAG is an engineering discipline more than a modelling one — you use pre-trained embedding and language models rather than training your own. Comfortable Python is the real prerequisite; the course teaches the embedding, retrieval and evaluation concepts as you meet them.
Load a set of PDFs, chunk and embed them in ChromaDB, and build a command-line assistant that answers questions strictly from their contents and says so when it cannot.
Embed the same corpus with three models — Hugging Face open-source, OpenAI and a small local model — and measure retrieval hit rate, latency and cost to justify a choice.
Build a cited Q&A assistant over a company’s policies and manuals in Pinecone, with metadata filters by department and an incremental re-indexing pipeline for updated documents.
Add query rewriting, BM25 keyword search and a cross-encoder re-ranker to an existing retriever, then prove the improvement on a golden question set rather than by feel.
Build a test set from real user questions and score retrieval precision, answer faithfulness and relevance with LLM judges, wired into a regression suite that runs on every change.
A conversational assistant over a product’s documentation that keeps context across turns, streams answers, cites sources and escalates to a human when confidence is low.
Package a retrieval system as a FastAPI service with authentication, rate limiting, caching, tracing and a Docker image, deployed to the cloud and monitored under load.
Choose a real document set — a college’s regulations, a clinic’s protocols, a firm’s contracts — and deliver the full system: ingestion, index, hybrid retrieval, cited answers, evaluation report and a live deployment you present and defend.
The working loop
Every project moves through the same loop: understand the brief, build with guidance, then explain the decisions behind your work.
Break a real requirement into a clear plan and the right tools.
PDF Question-Answering Bot
Work hands-on with trainer feedback while the decisions are still easy to change.
Embedding Model Comparison
Turn the finished work into a portfolio story you can defend in an interview.
Company Knowledge Assistant
There are many places to learn this in Phagwara and the brochure syllabus looks similar at all of them. What differs is who teaches, whether you ever touch real work, and whether anyone picks up the phone after you have paid. techcadd has trained students across Punjab since 2007 on the same model: small batches, working practitioners as trainers, client projects as coursework.
Your trainer is not a full-time lecturer. They deliver client projects for techcadd’s services arm, so examples in class are current rather than a case study from five years ago.
You work on genuine client requirements under supervision. This is where a portfolio comes from, and it is the first thing an interviewer asks to see.
Batches stay small enough that a trainer sees your screen daily. Lab time runs outside class hours and doubt sessions continue until the concept lands.
Every student finishes with an industry-recognised certificate and a documented internship on real work, accepted for university industrial training requirements.
Mock interviews, CV reviews and drives with hiring partners across Phagwara, Jalandhar and North India, repeated after a rejection, not abandoned.
Nearly two decades of hiring relationships in Punjab is why a call from our placement cell gets answered and why local employers know what our certificate means.
What made it click for me was the lab time. You can sit after class and someone will still explain it until you get it.
I travelled in for the weekend batch and it was worth every trip. Small batch, real work, no time wasted on theory nobody uses.
The course got me interview-ready faster than I expected. My interviewer asked to see my project and that was the whole conversation.
I was switching careers and worried I would be behind. Half the batch was doing the same thing, and nobody made it awkward.
I joined with almost no background and finished with a project I could actually show. The trainer never rushed the basics.
techcadd’s placement cell kept calling me for drives until I was placed. That persistence mattered more than anything else.
It is a specialist programme on building AI applications that answer from your own documents rather than from a model’s memory. You learn document parsing and chunking, embeddings, vector databases like Pinecone and ChromaDB, query rewriting and re-ranking, grounded answers with citations, evaluation and hallucination testing, and production deployment with FastAPI — built as one real system across the course.
One call with a counsellor is usually enough to find out. Book a free demo class and see the lab before you decide.
Send your question and a counsellor will call you back about batch timings, fees, EMI options, placement record, or whether this course fits your degree.